RAG vs Fine-Tuning: Which Strategy is Right for Your LLM?
Updated at May 8, 2026
13 min to read
.webp)
Most AI models sound smart. Few actually know what they are talking about.
That is the gap Retrieval-Augmented Generation (RAG) is solving. Instead of relying only on training data, RAG systems retrieve real, relevant information before generating responses, making outputs far more accurate and reliable.
This shift is what’s driving the rise of real-world RAG applications across industries. From customer support automation to enterprise knowledge assistants, businesses are using RAG to solve problems where context and precision matter.
In this guide, you will explore 10 practical RAG use cases and real-world examples, along with how they are applied in healthcare, e-commerce, education, and enterprise AI.
If you’re using an AI model without RAG, you’re asking it to guess. And that’s the problem.
RAG stands for Retrieval-Augmented Generation.
It’s a method that helps AI models pull in relevant, accurate information just-in-time, so they can answer questions with facts, not guesses.
A rag application makes your chatbot, assistant, or AI tool smarter by connecting it to live data before generating a response. That’s the core idea.
You don’t need to retrain the model. You don’t need to rewrite prompts. RAG gives you relevance from day one.
A RAG application is what happens when you take RAG technology and deploy it inside a real product, a chatbot, a search tool, a support assistant, or an internal knowledge base. Where RAG is the method, a RAG application is the outcome. It's the thing your users actually interact with, powered by retrieval behind the scenes
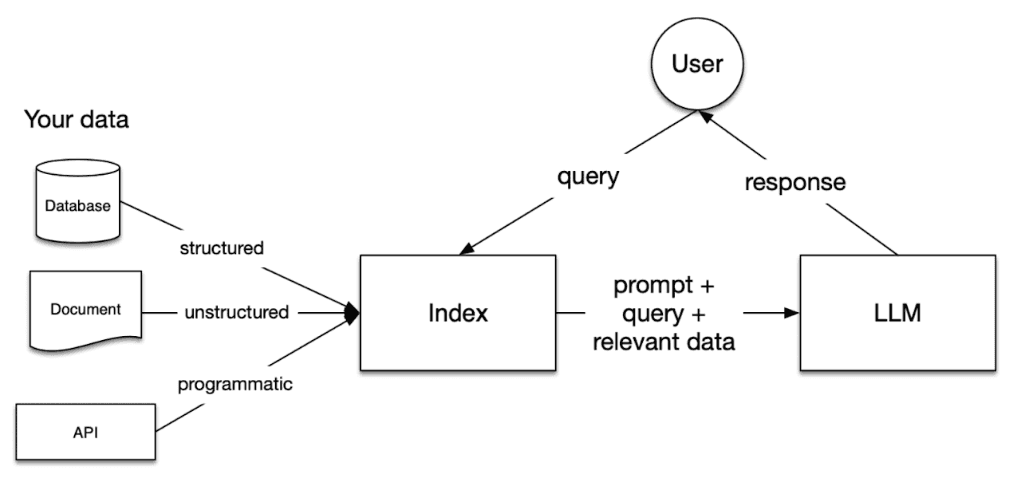
Here’s what happens inside a typical rag application:
User → Question → Retriever → External Data → LLM (Generator) → Final Response
Let’s break it down:
That’s how the best rag examples deliver sharp, grounded answers, without training or manual tuning.
Prompt engineering is hit or miss. Fine-tuning takes time, money, and lots of labeled data.
RAG skips both.
It gives your AI model live access to the right info. No need to bake everything into the model. No need to guess what prompt trick will work.
If your product, chatbot, or assistant depends on fast, factual answers, a rag use case is your most reliable play.
RAG is faster to build, easier to maintain, and better at scaling across topics or use cases.
RAG vs Agentic AI: What Is the Difference?
Most teams confuse these two. Here is the clean distinction.
RAG retrieves relevant information from a knowledge base and uses it to generate one accurate response. It is a single-step enhancement to an LLM.
Agentic AI plans, reasons, and executes across multiple steps autonomously. It can browse the web, write code, call APIs, and make decisions without human input at each stage.
The key difference: RAG answers. Agentic AI acts.
Most production RAG applications today are actually components inside larger agentic systems; RAG handles the knowledge retrieval while the agent handles the decision-making around it.
Everyone’s using AI. But very few are using it well.
Language models are trained on massive public datasets. But they don’t know your product manuals, customer chats, or internal wikis.
So when they’re asked something specific, they guess.
That’s the gap. And it shows up in search engines that return junk, chatbots that can’t help, and assistants that sound confident but give wrong answers.
Fine-tuning a model takes weeks. It costs money. And the moment your content changes, it’s outdated again.
Prompt tricks? They’re brittle. You can’t build serious products on guesswork and workarounds.
This is why more teams are moving to RAG. A rag application doesn’t need a new model or a rewrite. It connects your data to the AI, so answers stay useful and up-to-date.
RAG searches your actual content, then feeds that into the model in real time.
The model responds with context, not guesses. That changes everything.
Chatbots can answer based on internal policies. Virtual assistants pull from the latest docs. Search tools actually understand how your users speak.
Teams using rag use cases are launching faster, scaling smarter, and spending less time maintaining fragile systems.
They're not building AI experiments. They're building products that work.
RAG applications are no longer experimental. Across customer support, healthcare, e-commerce, education, and SaaS, companies are deploying RAG use cases in production right now. These are not proofs of concept. These are live systems cutting costs, reducing errors, and delivering faster answers at scale.
Here are 10 real-world RAG application examples showing exactly how it works — and what it takes to build one.
Customer support is where RAG applications deliver the fastest, most measurable ROI. The answers already exist somewhere in your docs, tickets, or knowledge base. RAG retrieval augmented generation connects that knowledge directly to the user instantly.
This RAG application turns your existing help documentation into a live, intelligent support agent.
Instead of a customer waiting for a human to search through manuals or escalate a ticket, they ask a question, and get a precise, sourced answer in seconds. The system retrieves the most relevant chunks from your knowledge base, feeds them to the language model, and returns a response grounded in your actual content.
No hallucinations. No outdated answers. No guessing.
Why RAG is Useful Here
Traditional support chatbots fail because they rely on pre-programmed flows or static training. The moment your product changes, your docs change, or a new policy goes live; the bot is already wrong.
RAG solves this by retrieving from your live knowledge base at query time. It doesn't need retraining every time something changes. The content updates. The answers update automatically.
This RAG use case is the highest-ROI starting point for most businesses, especially those handling repetitive support volume at scale.
Real-World Example
A SaaS company handling 10,000+ monthly support tickets deployed a RAG-powered customer support chatbot connected to their full help documentation.
As a result, ticket resolution became faster, while first-contact resolution climbed. Human agents fielded fewer repetitive queries and focused more on complex escalations.
That is the compounding impact of a RAG application that answers from your data.
With BotPenguin: BotPenguin's RAG chatbot connects to your existing knowledge base and deploys across your website, WhatsApp, and Telegram, without retraining every time your docs change.
This RAG application doesn't replace your human agents; it makes them significantly faster.
When a customer is mid-conversation with a live agent, the system listens in real time and surfaces the most relevant internal documents, past resolutions, and policy excerpts automatically. The agent gets the right answer without switching tabs, searching wikis, or putting the customer on hold.
Why RAG is Useful Here
The average support agent switches between 4 to 6 tools during a single customer conversation. That friction adds up: longer handle times, more escalations, higher frustration on both sides.
RAG eliminates the search step entirely. The retrieval happens in the background. The agent stays in the conversation. The customer gets a faster, more confident answer.
This RAG use case is especially valuable for complex products, regulated industries, or teams with high agent turnover, where institutional knowledge is hard to transfer quickly.
Real-World Example
A retail support team integrated a RAG-powered escalation assistant directly into their Zendesk dashboard. The system retrieved relevant policy documents and past ticket resolutions as customers typed.
Average handle time shrank, and fewer cases demanded senior escalation. New agents also hit productivity faster because the system surfaced relevant institutional knowledge.
With BotPenguin: BotPenguin's unified inbox combines live agent support with RAG retrieval, giving your team instant context without leaving the conversation window.
Healthcare is one of the highest-stakes environments for AI. Answers must be accurate, current, and sourced. RAG applications in healthcare retrieve exclusively from approved, controlled knowledge bases, making them significantly safer than standard LLM deployments where the model generates from unchecked training data.
This RAG application connects clinicians to peer-reviewed research, drug interaction databases, and clinical guidelines, at the moment they need them, not after a manual search.
A doctor queries a condition. The system retrieves the most relevant medical literature, filtered by patient age, co-morbidities, and drug safety data. The model synthesizes it into a clear, actionable summary. The clinician gets structured insight in seconds instead of minutes.
Why RAG is Useful Here
Medical knowledge is vast, constantly updated, and high-stakes. No clinician can hold all of it in memory. And searching PubMed mid-consultation is not realistic.
Standard LLMs are dangerous here; they generate from training data that may be outdated, unverified, or missing critical safety nuances. RAG solves this by retrieving only from your approved, current, controlled knowledge bases. Every answer is traceable back to a source document.
This RAG use case doesn't replace clinical judgment. It sharpens it.
Real-World Example
A hospital network deployed a RAG-based clinical decision support tool integrated directly into their EHR system. Clinicians queried patient conditions and received peer-reviewed research summaries filtered by patient profile in real time.
Diagnostic consultation moved faster, while clinicians reported greater confidence in complex cases. The system pulled from a curated, institution-approved knowledge base.
With BotPenguin: BotPenguin enables healthcare teams to deploy RAG assistants using approved medical knowledge bases. BotPenguin is GDPR, HIPAA, and CCPA compliant, ISO certified, SOC 2 attested, and VAPT-assessed by a CERT-In empanelled auditor. We can also help your business achieve these compliance standards.
This RAG application handles the flood of repetitive patient queries that consume front-desk staff time every single day.
Appointment availability, insurance coverage, pre-procedure prep, clinic policies: these are answerable questions. The answers already exist in your documentation. A RAG application retrieves and delivers them instantly, 24 hours a day, without a staff member picking up the phone.
Why RAG is Useful Here
Front-desk teams in healthcare are stretched thin. A significant portion of their day is spent answering the same 15 questions in different variations. That is time that should go toward patients who genuinely need human attention.
RAG changes the economics of patient communication. It retrieves from your actual intake forms, appointment systems, and policy docs, so every answer is accurate to your clinic, not generic AI output. And it never calls in sick.
Real-World Example
A multi-location clinic deployed a RAG-powered patient FAQ bot across their website and WhatsApp. The bot handled appointment queries, insurance questions, and pre-visit instructions automatically.
Incoming front-desk calls decreased, while patient satisfaction rose. Staff could spend more time on in-clinic patient care instead of routine phone queries.
With BotPenguin: BotPenguin's healthcare chatbot handles patient queries around the clock using your own approved clinic documentation, freeing your front-desk team for interactions that actually need a human.
In e-commerce, every second of friction costs revenue. RAG applications in retail connect AI directly to live product data, order systems, and customer history, making every interaction relevant, accurate, and fast. These RAG use cases directly impact conversion rate, average order value, and post-purchase retention.
This RAG application turns your product catalog into a personalized shopping assistant that knows what is actually in stock.
A customer describes what they are looking for. The system retrieves live product data: specs, availability, reviews, variants, and generates a recommendation that fits their exact need. Not a pre-set flow. Not last month's training data. Live retrieval, every time.
Why RAG is Useful Here
Generic recommendation engines suggest based on broad purchase patterns. They don't know a specific customer's constraints: budget, size, use case, compatibility. And they definitely don't know your real-time inventory.
RAG closes that gap. It retrieves from your live product database at the moment of the query. If a product is out of stock, the system knows. If a better variant exists, the system surfaces it. The result is a recommendation that actually converts.
This RAG use case has a direct, measurable impact on revenue, which is why it's one of the fastest to justify in e-commerce.
Real-World Example
An e-commerce brand integrated a RAG-powered product recommendation assistant on their product and category pages. The assistant retrieved live catalog data and generated personalized suggestions based on each visitor's browsing context and stated needs.
Add-to-cart activity climbed, while average order value also grew. Returns dropped because customers received recommendations better matched to their needs.
With BotPenguin: BotPenguin connects directly to your product catalog and gives shoppers personalized, real-time recommendations based on what is actually available, not pre-trained assumptions.
This RAG application handles the single most common e-commerce support query: “where is my order?”, without routing it through a human agent.
The customer asks. The system retrieves live order status, carrier tracking data, and return policy information in real time. The answer is specific, accurate, and instant.
Why RAG is Useful Here
Post-purchase queries are high volume, low complexity, and entirely solvable by a system. Yet most brands still route them through human agents, creating unnecessary cost and unnecessary wait time.
RAG makes this effortless. It retrieves from your live order management system and returns the exact status, not a generic response. When a customer asks about a return, it retrieves your actual return policy, not a hallucinated version of it.
This RAG use case is one of the easiest to implement and one of the fastest to reduce support overhead.
Real-World Example
A Shopify store processing 5,000 orders per month deployed a RAG-powered post-purchase bot connected to their order management system and carrier APIs.
Post-purchase support tickets decreased, while customer satisfaction rose. The support team could focus more on complex returns and disputes instead of routine order-status queries.
With BotPenguin: BotPenguin integrates directly with your order management system and delivers live order updates to customers automatically across WhatsApp, website chat, and more.
Education institutions manage enormous volumes of documentation: course catalogs, admission criteria, policies, faculty handbooks, spread across outdated portals and PDFs nobody can find. RAG applications in education make that knowledge instantly accessible, for both students and staff.
This RAG application handles the flood of recurring queries that admissions teams receive from prospective and current students at any hour, without adding headcount.
A student asks about scholarship eligibility, application deadlines, or course prerequisites. The system retrieves from your actual admissions documentation and returns a precise, current answer. No more "please check the website" responses that send students in circles.
Why RAG is Useful Here
Admissions teams deal with the same questions in hundreds of variations every cycle. The answers exist; they are buried in PDFs, FAQs, and course catalog pages that students can't navigate efficiently.
RAG retrieves from those sources directly. It understands the question, finds the right document, and generates a clear answer. As documentation updates, so do the answers. No manual retraining required.
This RAG use case directly minimizes staff workload during peak admission periods and improves the prospective student experience at a critical decision point.
Real-World Example
A university deployed a RAG-powered admissions assistant across their website and WhatsApp during their annual enrollment period. The bot retrieved from over 400 pages of admissions documentation and handled queries in real time.
Many admissions queries got resolved without human intervention, while response times improved significantly. The admissions team could focus more on high-value applicant outreach.
With BotPenguin: BotPenguin's education chatbot answers student queries 24/7 using your actual admissions documentation, and deploys in days, not months.
This RAG application gives faculty and administrative staff instant access to the internal knowledge they need, without searching across five different portals.
HR policies, curriculum guidelines, procurement procedures, IT documentation: all of it lives somewhere. RAG retrieval augmented generation connects those sources into one interface and surfaces the right answer on demand.
Why RAG is Useful Here
Educational institutions are some of the most document-heavy environments in existence. Policies update. Handbooks get revised. Governance documents accumulate across SharePoint, Google Drive, and email threads nobody archived properly.
Staff waste significant time searching for things that should take thirty seconds to find. IT and HR teams receive duplicate questions daily because people cannot locate the right document themselves.
RAG eliminates that friction. It retrieves from your actual institutional knowledge, however scattered it is, and delivers direct answers in natural language.
Real-World Example
A school district with 200+ staff members deployed a RAG-powered internal knowledge assistant connected to their HR documentation, IT help desk guides, and policy handbooks.
Internal IT and HR support load eased, while staff onboarding sped up. Employees could find answers without waiting for a senior colleague to respond.
With BotPenguin: BotPenguin's education chatbot can be deployed internally for staff as easily as it deploys for students, connecting to your institutional knowledge base and answering queries across MS Teams, Slack, or your intranet portal.
SaaS companies run on documentation: product docs, API references, internal wikis, onboarding guides. RAG applications in SaaS make that documentation useful in real time, for both internal teams and end users. These RAG use cases reduce churn, speed up development cycles, and eliminate the institutional knowledge problem that every scaling tech company faces.
This RAG application connects your engineering team to every piece of internal documentation: API docs, architecture decisions, Confluence pages, Slack threads, through a single, intelligent interface.
A developer asks a question. The system retrieves from your actual internal knowledge stack and generates a direct answer. No more "check the wiki" responses that lead to a page last updated in 2022.
Why RAG is Useful Here
Engineering teams at scale waste enormous amounts of time searching for answers that already exist internally. Duplicate Slack questions. Repeated architecture discussions. New hire onboarding that drags because institutional knowledge lives in people's heads, not in accessible systems.
RAG surfaces that knowledge on demand. It retrieves from your actual codebase comments, internal docs, past incident reports, and architecture decision records, and gives developers the answer without interrupting anyone else.
This RAG use case directly reduces developer context-switching and compresses the time it takes new engineers to become productive.
Real-World Example
A scaling tech company with 150 engineers deployed a RAG-powered internal assistant connected to their Confluence wiki, GitHub docs, and Slack archive. Engineers queried it through a Slack bot interface.
Duplicate Slack questions dwindled, while new engineers ramped up faster. Senior engineers spent less time answering repeated internal questions and more time on development work.
With BotPenguin: BotPenguin connects to your internal knowledge stack and gives developers instant, accurate answers without leaving their workflow, deployable via Slack, MS Teams, or a custom internal portal.
This RAG application guides new users from signup to their first value moment, using your actual product documentation, not generic onboarding scripts.
A new user gets stuck. Instead of opening a support ticket or bouncing, they ask the onboarding assistant. The system retrieves the exact help article, tutorial step, or configuration guide they need, and delivers it in plain language at the right moment.
Why RAG is Useful Here
Churn during onboarding is the most expensive churn in SaaS. Users who don't reach their first value moment within the first week rarely come back. And the reason is almost always the same; they couldn't find the right help fast enough.
Standard onboarding flows are linear. RAG is adaptive. It retrieves based on what the user is actually asking, not what the product team assumed they would ask. It works for every user type, every use case, and every edge case your documentation already covers.
This RAG use case has a direct impact on activation rate, time-to-value, and ultimately, retention.
Real-World Example
A B2B SaaS platform with a complex product and a 14-day trial window deployed a RAG-powered onboarding assistant connected to their full help documentation and video tutorial transcripts.
Time-to-activation improved, trial-to-paid conversion climbed, and new-user support tickets decreased. Users could get answers directly from the product instead of the support queue.
With BotPenguin: BotPenguin's onboarding assistant retrieves from your help docs and guides new users to their first value moment faster, reducing churn before it starts.
RAG applications typically combine business data sources with retrieval infrastructure and a large language model. The stack depends on the use case, but generally includes:
Every use case above solves the same root problem: valuable knowledge trapped where people can't reach it fast enough. RAG fixes that. The only question is where you start.
Most teams overcomplicate this. The right RAG use case is almost always the one that solves the most painful, most repetitive problem your team faces today.
Not every RAG solution fits every business. Here’s how to choose the rag application that actually solves your problem, without wasting time or budget.
Before choosing any rag use case, get clear on the core frustration you're solving.
RAG works best when there’s a clear signal: high volume, repetitive questions, or slow access to information. That’s your cue.
A good rag application isn’t just cool tech; it fits where your users already are.
Use RAG to improve workflows, not add new ones.
RAG thrives on unstructured content: PDFs, docs, transcripts, wikis.
Think about where your “answers” live and whether they’re ready to retrieve.
The best rag applications don’t just automate. They reduce confusion.
Use cases like:
These drive instant value by turning complexity into clarity. If it replaces a meeting, email, or long search; it’s a strong candidate.
Look at your current stack: CRM, ERP, LMS, Helpdesk, Search.
Many rag examples start by connecting to tools teams already use, then layering a conversational interface or better retrieval logic.
No need to rip and replace. Start by enhancing what already exists.
You don’t need to deploy across your org on day one.
The most successful rag applications start small: solving one painful, high-impact problem in one department.
Prove it. Scale it. Then expand.
Need inspiration? Scroll back up to the 10 real-world rag use cases above. Each one is a blueprint waiting to be tailored to your needs.
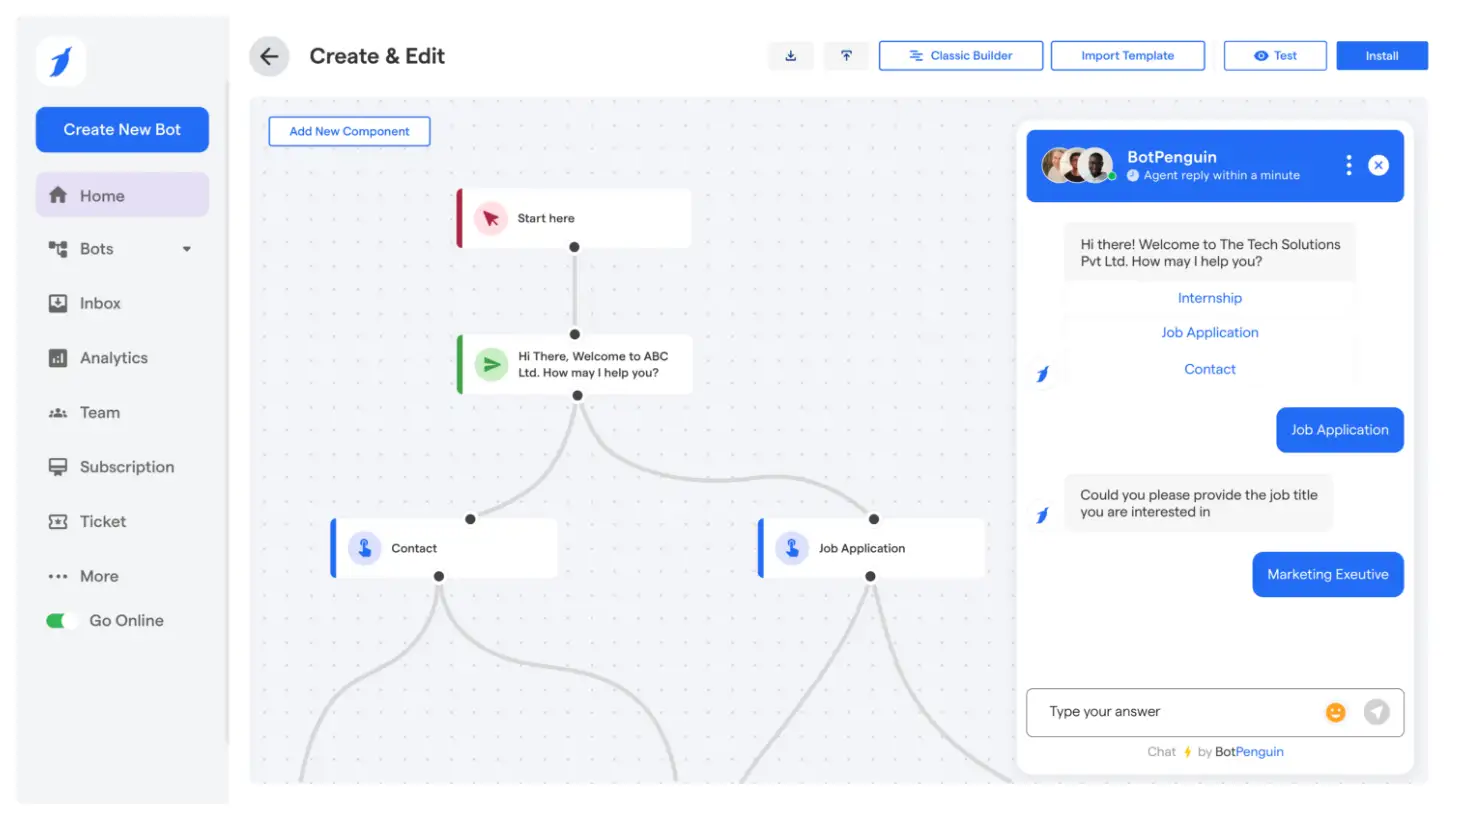
Every rag use case you've seen above? From support bots and product advisors to internal search agents and CRM copilots; they can all be delivered through one tool: BotPenguin.
BotPenguin isn't just another chatbot builder.
It's a RAG-ready AI agent platform, built to connect your data with LLMs, answer questions accurately, and deliver it all through natural, human-like conversation.
If you're sitting on support docs, product manuals, customer data, or internal content, BotPenguin turns that into instant, useful responses. And it works where your users are: web, WhatsApp, Messenger, and more.
Here’s what happens when you pair a smart retrieval engine with a powerful AI agent:
You don’t need to start from scratch. You just connect your data and go. That’s what makes BotPenguin one of the easiest ways to launch a RAG chatbot today.
BotPenguin can deliver your project, right now.
And how you use it? That’s up to you.
Turn it into a smart support agent. A lead qualifier. A self-serve onboarding guide. A policy navigator.
One agent. All your use cases. Powered by RAG.
👉 Try BotPenguin now, and launch in minutes.
Don’t build a chatbot. Build an AI that actually helps.
A RAG (Retrieval-Augmented Generation) application is an AI system that combines a retrieval engine with a large language model. Instead of relying solely on pre-trained knowledge, it searches external data sources, like documents, databases, or websites, and uses that retrieved content to generate accurate, fact-grounded responses in real time.
The most common RAG use cases include customer support chatbots that answer from help docs, internal knowledge assistants for enterprise teams, clinical decision support in healthcare, financial compliance Q&A systems, legal document search, e-commerce product recommendations, and HR onboarding assistants. RAG is used wherever AI needs to answer accurately from private or frequently updated data.
A RAG pipeline is the end-to-end workflow that powers a RAG application. It includes five steps: data ingestion (loading and chunking documents), embedding (converting chunks into vectors), storage (saving vectors in a database like Pinecone or ChromaDB), retrieval (finding relevant chunks for a user query), and generation (passing retrieved content to an LLM to produce the final response).
RAG retrieves relevant information from a knowledge base and uses it to generate a single, grounded response. Agentic AI goes further; it can plan multi-step tasks, use tools, browse the web, write code, and make decisions autonomously. RAG is a component that agentic AI systems often use, but agentic AI has broader reasoning and action capabilities beyond retrieval alone.
Fine-tuning retrains a language model on new data to change its behavior permanently; it is expensive, time-consuming, and must be repeated whenever your data changes. RAG does not modify the model at all. Instead, it retrieves up-to-date information at query time and feeds it into the model as context. RAG is faster to build, easier to maintain, and more cost-effective for most business use cases.
The main disadvantages of RAG include poor retrieval quality if documents are not chunked and embedded correctly, increased response latency due to the retrieval step, the need to maintain an up-to-date vector database, and the risk of generating incorrect answers if retrieved content is irrelevant or outdated. Building a production-grade RAG system also requires more infrastructure than a basic LLM API call.
ChatGPT in its base form is not a RAG application, it generates responses purely from pre-trained knowledge without retrieving external documents. However, ChatGPT with browsing enabled or connected to external data via custom GPTs does use retrieval mechanisms similar to RAG. Purpose-built RAG applications differ because they retrieve from specific, controlled, private knowledge bases rather than the open web.
Subscribe to Our Newsletter
Get the latest business insights straight into your inbox.
Checkout our related blogs you will love.
Updated at May 8, 2026
13 min to read

Updated at Feb 19, 2026
14 min to read
Updated at Aug 20, 2026
10 min to read
Updated at Aug 20, 2026
12 min to read
Updated at Aug 20, 2026
10 min to read
Updated at Aug 19, 2026
11 min to read
Table of Contents